EmoMM: Benchmarking and Steering MLLM for Multimodal Emotion Recognition under Conflict and Missingness
Jul 2, 2026·,,,,,,,
Yueru Sun
Yimeng Zhang
Haoyu Gu
Nuo Chen
Dong She
Xianrong Yao
Yang Gao
Zhanpeng Jin
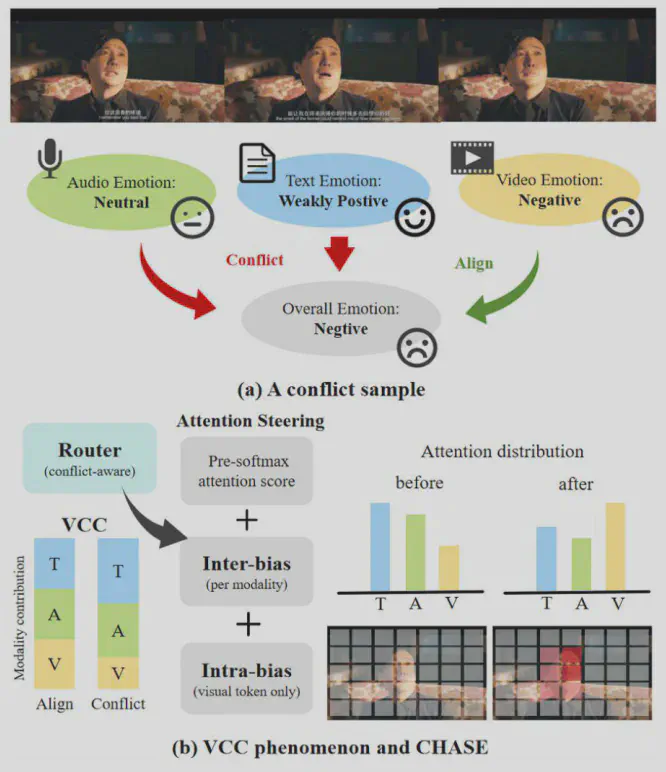 Figure 1 from the paper.
Abstract
EmoMM benchmarks multimodal emotion recognition when audio, video, and text agree, conflict, or are missing. The study identifies Video Contribution Collapse, in which models underuse visual evidence. Conflict-aware Head-level Attention Steering (CHASE) adjusts attention at inference time to improve robustness without retraining the model backbone.
Type
Publication
Findings of the Association for Computational Linguistics: ACL 2026 (ACL 2026 Findings), pp. 20351–20371